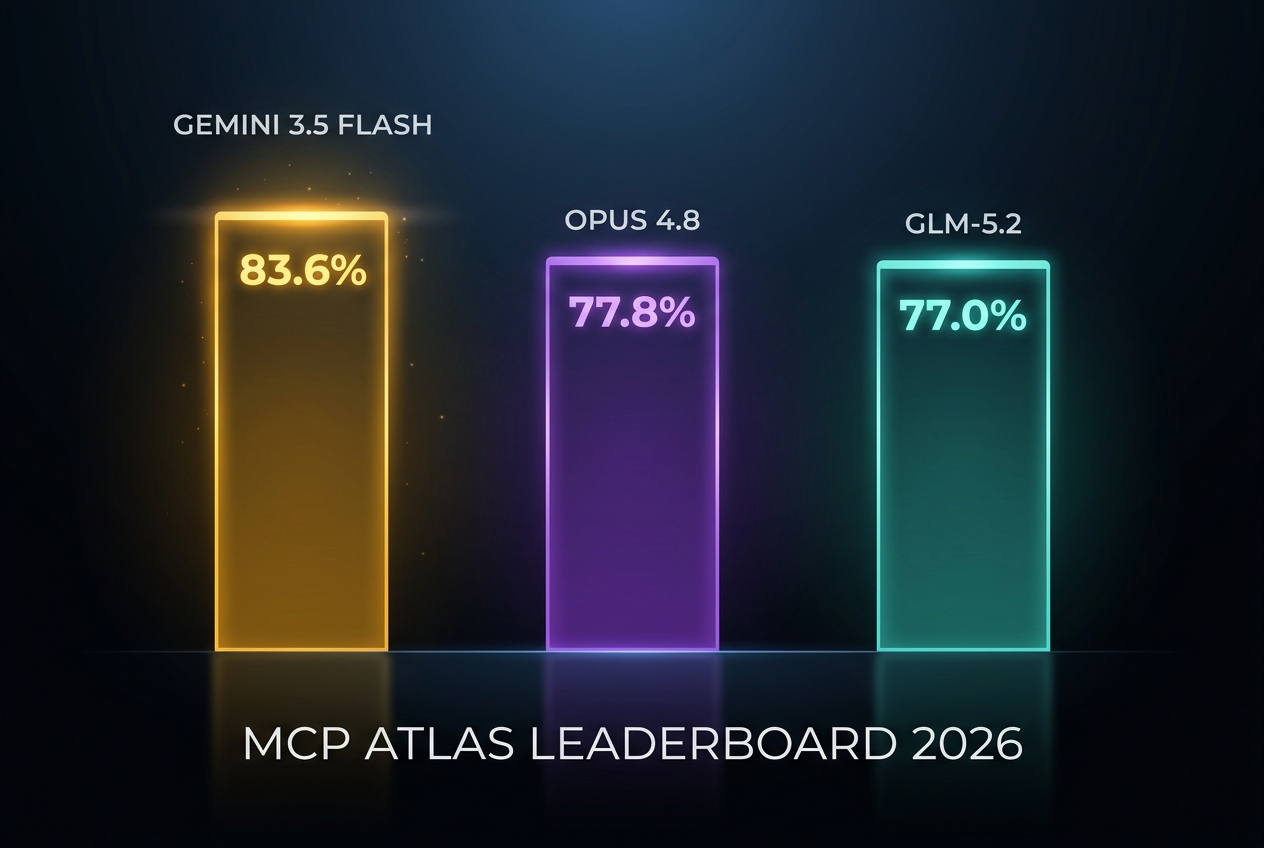
MCP Atlas Leaderboard
Multi-server tool orchestration. 36 real MCP servers, 1,000 tasks, claims-based scoring. The benchmark that tests what AI agents actually do — chain tools together correctly.
Last updated: October 16, 2026 · Added Step 5 Preview at 85.6% (StepFun-reported evaluation); separate from Scale's 87.2% Fable 5.1 snapshot and Meta's 90.3% Muse Spark 1.2 run · SWE-bench Pro → · Terminal-Bench →
#
Model
Prov
Score
License
$/1M Out
Released
Src
MCP Atlas Score Comparison
Vendor-published scores; hover to inspect the source. Cross-harness results are directional.
About MCP Atlas: 1,000-task benchmark across 36 real MCP servers. Tests multi-step tool orchestration — calling the right API, in the right order, with the right parameters. Scale's April 2026 update replaced a 20-turn limit with a 100 tool-call budget and claims-based scoring.
🆕 Ornith-1.5-397B (80.0%): Ornith's model card reports a run on the 500-task public subset with all models in thinking mode, a 10-minute task timeout, and Claude Opus 4.8 as judge. It is a vendor result, distinct from Scale's standardized snapshot; the model is MIT-licensed/self-hosted and has no published API rate.
⚠️ Methodology note: Scores below come from different vendors using their own evaluation scaffolds. Scores from different sources are NOT directly comparable — a 83.6% from Google's harness vs 83.3% from Anthropic's harness doesn't mean one model is definitively better. Within a single lab's table (e.g., Z.AI's cross-model table), scores ARE comparable.
🆕 Muse Spark 1.2 leads at 90.3% in Meta's official evaluation (Muse Code harness) — the highest published vendor score to date. Claude Opus 5 scores 85.8% (Anthropic harness, xhigh), independently mirrored by Scale SEAL at 85.8% ± 2.1. Muse Spark 1.1 (88.1%) remains Meta's previous-generation result, ahead of Gemini 3.5 Flash's 83.6% vendor figure. Kimi K3 scores 84.2% on Moonshot's 500-task public subset with a 100-turn limit and Gemini 3.1 Pro as judge. Because these use different subsets and scaffolds, the ordering is directional rather than a controlled head-to-head. 🆕 Muse Glimmer (75.5%) is Meta's open-weight 30B (Apache 2.0, Aug 10, 2026); its Meta-reported result is the strongest published sub-100B open-weight score, ahead of Qwen3.6-27B (62.5%) and Gemma4-31B (54.2%). Step 5 Preview (85.6%) is a separate StepFun-reported high-thinking result, not a Scale standardized row; API list price is $1/$2.70 per 1M input/output tokens.
Test tool orchestration on real MCP servers
20+ LLMs on CodingFleet. Run your own MCP tool chains. Benchmarks are directional — your codebase is the real test.
🚀 Try on CodingFleet →Sources & Links
- Meta Muse Spark 1.1 model page — MCP Atlas 88.1%, Terminal-Bench 2.1 80.0%, SWE-bench Pro 61.5%
- Meta Muse Spark 1.2 model page — MCP Atlas 90.3% (Muse Code), Terminal-Bench 2.1 82.9%, DeepSWE 55.0%
- Meta Muse Glimmer model page — MCP Atlas 75.5% (high reasoning), SWE-bench Pro 51.2%
- BenchLM — Claude Opus 5 profile — MCP Atlas 85.8% from Anthropic's Opus 5 system card
- Scale Labs MCP Atlas leaderboard — Sep 23 snapshot: Claude Fable 5.1 87.20% ±2.05; Opus 5 85.8% ±2.1; Inkling-Small 79.2% ±2.5
- Moonshot AI Kimi K3 launch and benchmark table — MCP Atlas 84.2% on the 500-task public subset
- Anthropic System Card — Claude Fable 5 & Mythos 5 — Fable 5: 83.3%, Opus 4.8: 82.2% (Anthropic harness)
- Google Model Card — Gemini 3.5 Flash — 83.6% (Google harness)
- Z.AI Cross-Model Table (VentureBeat) — GLM-5.2, Opus 4.8, GPT-5.5, GLM-5.1, Gemini 3.1 Pro (Z.AI harness)
- Qwen Official Blog — Qwen 3.7 Max (76.4%), Opus 4.6 (Qwen harness)
- VentureBeat — MiniMax M3 analysis
- DeepSeek V4 Pro Model Card
- Scale SEAL MCP Atlas Leaderboard — standardized evaluation methodology
- Zvi Mowshowitz — Fable 5 & Mythos 5 capabilities