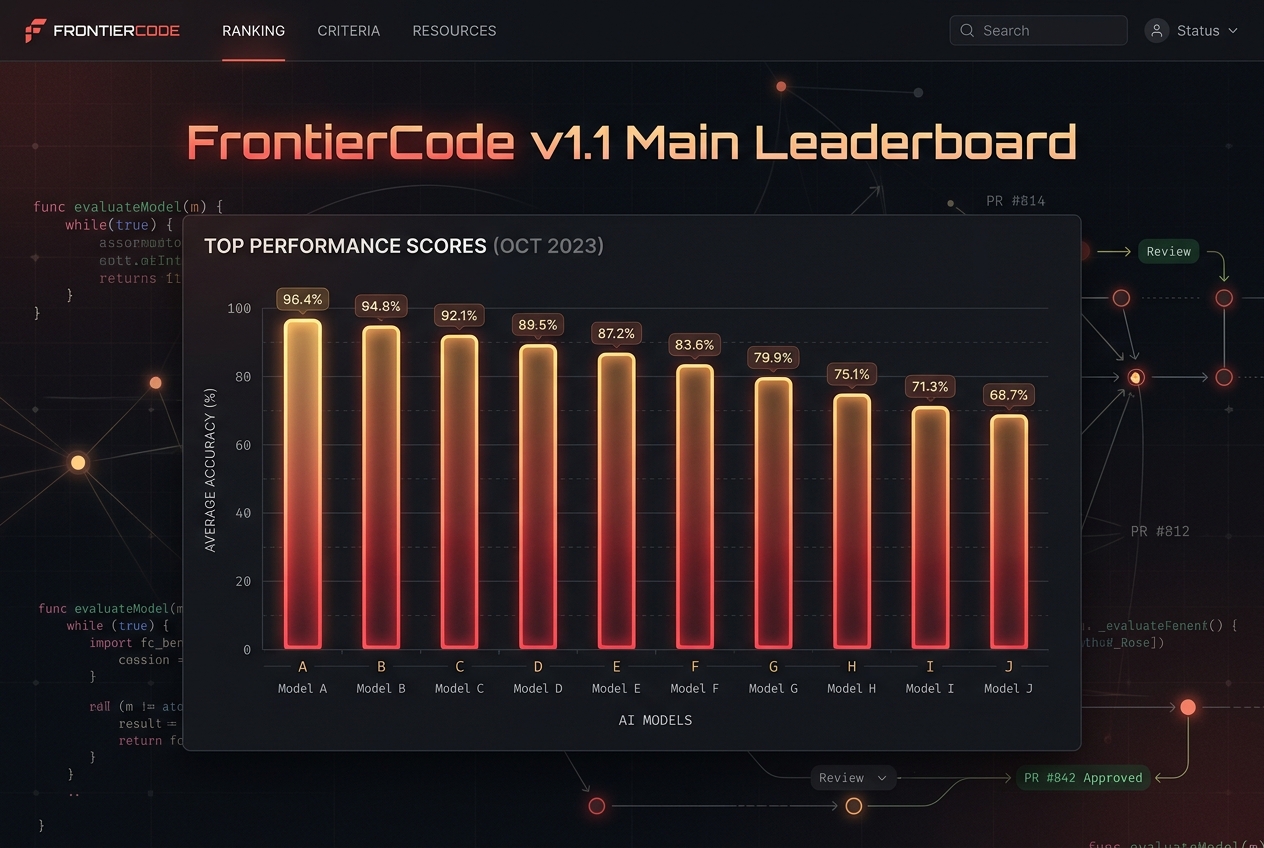
FrontierCode v1.1 Main Leaderboard
Production-code quality benchmark by Cognition. 100 private tasks scored by maintainer-authored rubrics — correctness, tests, scope, style, and maintainability. Models ranked by published Main scores.
Last updated: October 9, 2026 · 🆕 Cognition’s live Main board adds GPT-6.1 Sol at 50.2% (medium, $0.36/rollout) and Haiku 5.5 at 46.4% (max, $1.33/rollout); Opus 5.5 remains #1 at 54.6% · Source: Cognition FrontierCode · SWE-bench Pro → · Terminal-Bench →
#
Model
Prov
Main
Harness
License
$/1M Out
Source
Src
FrontierCode v1.1 Main Score Comparison
Published Main scores on a consistent 0–100 scale. Models without a score are omitted.
About FrontierCode v1.1: Cognition's production-code benchmark. Tests whether AI-generated pull requests are mergeable — scored for correctness, tests, scope, style, and maintainability through maintainer-authored rubrics. 100 private Main tasks (150 in Extended). Each row combines a model with an agent harness at its best-performing effort.
🆕 Cognition board refresh (checked Oct 9; Haiku 5.5 added Oct 7): Claude Opus 5.5 leads FrontierCode 1.1 Main at 54.6% (medium, $0.80 mean cost per rollout, 18.5k tokens). Sonnet 5.5 scores 52.1% (xhigh, $1.59/run, 47.4k tokens); GPT-6.1 Sol is 50.2% (medium, $0.36/run, 11.4k tokens); Haiku 5.5 posts 46.4% (max, $1.33/run, 181.4k tokens). Other board rows include SWE-2 (50.0%, $1.18/run), GPT-6 Sol (49.3%, $2.07/run), and Grok 4.7 (47.6%, $6.65/run). Rollout spend is distinct from API token rates. Haiku API price is $0.10/$0.50 per 1M input/output for prompts up to 100K tokens ($0.50/$2.50 above that threshold).
Anthropic’s separate launch report: Opus 5.5 scores 54.4% at max effort on its own FrontierCode run. Keep that provider run distinct from Cognition’s 54.6% medium-effort leaderboard configuration.
Separate Extended-set result (not ranked in this Main table): Cognition’s Devin release note reports GPT-6.1 Sol at 60.4% on FrontierCode 1.1 Extended, in line with GPT-6 Sol (60.7%). GPT-6.1 Sol’s medium-effort rollout cost was $0.31; Extended scores are not comparable to the 100-task Main scores above. Source: Devin / Cognition.
🆕 GPT-5.6 Sol (47.5%): OpenAI's flagship scores 47.5% Main on the official Cognition leaderboard. Extended: 60.6%.
🆕 Grok 4.6 (48.0%): Ranks #3 on the official Cognition leaderboard — ahead of GPT-5.6 Sol — at high effort ($2.88/run). Gemini 3.7 Flash (43.6%) is the strongest Flash-tier result yet, +9.2 pts over 3.6 Flash, at medium effort ($3.65/run). Both landed the week of Aug 12–13, 2026.
🆕 New entries (Aug 2026): Kimi K3 (44.2%), Grok 4.5 (42.4%), GPT-5.6 Terra (41.3%), GPT-5.6 Luna (39.8%), Gemini 3.6 Flash (34.4%), DeepSeek V4 Flash 0731 (18.8%), DeepSeek V4 Pro (17.6%), MiniMax M3 (14.7%), Inkling 0.99 (14.0%), Mistral 3.5 Medium (8.0%), and Qwen 3.7 Plus (10.2%) all now have published Main scores on the official Cognition FrontierCode leaderboard.
Harness note: Scores combine different agent harnesses (claude-code, codex, SWE-agent). Results from different harnesses are directional rather than directly comparable.
📊 See also: SWE-bench Pro Leaderboard — real-world bug fixing | Terminal-Bench 2.1 Leaderboard — CLI coding | DeepSWE v1.1 Leaderboard — long-horizon engineering
Test these models on production code
20+ LLMs on CodingFleet. Run them on your own PRs. Benchmarks are a compass, not a map.
🚀 Try on CodingFleet →